Fan-out tail latency calculator
/tools/fan-out-tail/A request fans out to N calls and waits for all of them. See how many requests are slow, and what percentile each call needs to meet your target.
A request fans out to N calls and waits for all of them. See how many requests are slow, and what percentile each call needs to meet your target.
A request that fans out to several calls, to shards, backends or one service called many times, and waits for all of them, is slow whenever any one of those calls is slow. Calls that are slow only 0.5% of the time make 9.54% of requests slow once a request makes 20 of them. This tool gives you that number, and works backwards to the percentile each call needs for your request to meet its own target.
| Input | What to enter |
|---|---|
| Calls per request | How many calls one request makes and waits for |
| Each call is slow | The share of calls over your latency limit, such as 0.5%. Or the percentile at that limit: p99 means 1% of calls are over it |
| Your target | The percentile you promise for the whole request, such as p99 |
| Several dependencies (optional) | Leave it empty for one kind of call. Fill it in when a request calls services with different tails; it then replaces the first two inputs |
“Slow” means over one limit, the time your request can afford to wait. If your target is a p99 under 300 ms, a call is slow when it takes longer than 300 ms, and you read each call’s share of slow calls off its own latency dashboard.
Press Run after changing the inputs. Start again (defaults) puts every input back as it was.
A search request fans out to 20 shards and waits for all of them. Each shard is over your 300 ms limit 0.5% of the time. Your target is a p99 under 300 ms. Enter:
| Input | Value |
|---|---|
| Calls per request | 20 |
| Each call is slow | 0.5% |
| Your target | p99 |
The tool answers:
Requests that wait for a slow call9.54%1 - (1 - 0.5%)^20  ·  a p99 target allows 1%
For p99 on the request, each call needs p99.95. Your calls are at p99.5.
Then a curve of slow requests against calls per request, with 20 marked: at 50 calls the same shards would slow 22.2% of requests, and at 100, 39.4%.
In plain words: one search in ten waits for a slow shard, nearly ten times what a p99 target allows. For 99% of searches to stay under 300 ms, each shard has to stay under it 99.95% of the time, about 1 call in 2,000 slow at most, which is a stricter percentile than most dashboards show.
A checkout service calls 12 dependencies: pricing 20 times, once per item in the basket, promotions twice, the session cache three times, and the other nine once each. Leave the first two inputs as they are and enter, under Several dependencies (optional):
cart 1 0.1%pricing 20 0.5%inventory 1 1%tax 1 0.2%shipping quotes 1 2%payments 1 0.5%fraud check 1 1%user profile 1 0.1%promotions 2 0.5%loyalty 1 0.3%recommendations 1 1%session cache 3 0.1%The tool answers:
Requests that wait for a slow call16.1%1 - (1 - 0.1%) × (1 - 0.5%)^20 × ... × (1 - 0.1%)^3  ·  34 calls to 12 dependencies  ·  a p99 target allows 1%
For p99 on the request, each of the 34 calls needs p99.97. Fix pricing first: its 20 calls slow 9.54% of requests on their own.| Dependency | Calls | Slow calls | Without it |
|---|---|---|---|
| pricing | 20 | 0.5% | 7.26% |
| shipping quotes | 1 | 2% | 14.4% |
| inventory | 1 | 1% | 15.3% |
| fraud check | 1 | 1% | 15.3% |
| recommendations | 1 | 1% | 15.3% |
The table, “Fix first: slow requests without each one, top 5 of 12”, shows the five that matter most. Shipping quotes has the worst share, 2%, but pricing does more damage because every checkout calls it 20 times: without its slow calls, slow checkouts would fall from 16.1% to 7.26%, and without shipping quotes’ only to 14.4%.
One per line, or several on a line separated by commas. The name comes first, then the calls per request, then the share of slow calls. The calls are optional and default to one.
| You write | It means |
|---|---|
pricing 20 0.5% | 20 calls per request, 0.5% of them slow |
pricing: 20 calls, 0.5% | The same |
tax 0.2% | 1 call, 0.2% slow |
shards 20 p99 | 20 calls, and your limit sits at each call’s p99, so 1% are slow |
auth 3x p99.9 | 3 calls, 0.1% slow |
A line starting with # is a comment.
A request is under your limit only if every one of its calls is. If the calls are independent, the chance that none of them is slow is the product of each call’s chance of being fast:
Dean and Barroso give the best-known example in The Tail at Scale (CACM, 2013): 100 servers, each slow one time in a hundred, and 63% of requests are slow. The sample “The Tail at Scale: 100 servers at their p99” is that example, and the tool gives 63.4%.
index.ts/** * Fan-out tail latency: a request that fans out to N calls and waits for all of them is slow whenever any one of * those calls is. So calls that are slow 1% of the time, at their own p99, make far more than 1% of requests slow * once there are many of them. Dean and Barroso put the canonical number on it in "The Tail at Scale" (CACM, 2013): * 100 calls, each slow one time in a hundred, and 63% of requests are slow. * * Two answers, always together, both from treating every call as an independent draw: * * - forwards: n calls each slow a share q of the time leave 1 - (1 - q)^n of requests with a slow one. With mixed * dependencies, n_i calls at q_i each, it is 1 - Π(1 - q_i)^(n_i); * - backwards: for a share p of requests to stay under the limit, every one of the n calls has to stay under it * with probability p^(1/n), which is the percentile each call needs. * * ⚠️ Independence is the assumption to doubt. Calls that share a host, a lock, a network path or a garbage-collection * pause are slow together. That bunches slow calls into fewer requests, so fewer requests are slow than this says, but * the slow ones are hit harder. This is the baseline to compare a measurement against, not a forecast. */import type { Cell, Output, Tool } from "@toolbench/sdk";
type Input = { calls: number; slow: string; target: string; dependencies: string };type Target = { p: number; name: string };
class InputError extends Error { readonly input: string; readonly at: number | undefined; readonly len: number | undefined;
constructor(message: string, input: string, at?: number, len?: number) { super(message); this.name = "InputError"; this.input = input; this.at = at; this.len = len; }}
const MAX_CALLS = 100000;const MAX_LINES = 50;/** The fix-first table stops here, so it stays a short answer and does not become an inventory. */const TABLE_ROWS = 5;
type Dependency = { name: string; calls: number; q: number };
/** 1 - Π(1 - q_i)^(n_i), kept exact for tiny shares by summing log1p and undoing it with expm1. */const slowRequests = (deps: Dependency[]) => -Math.expm1(deps.reduce((a, d) => a + d.calls * Math.log1p(-d.q), 0));const slowFrom = (q: number, n: number) => slowRequests([{ name: "", calls: n, q }]);
/** The share of each call that may be slow, if all n calls must be fast for a share p of requests to be. */const allowedPerCall = (p: number, n: number) => -Math.expm1(Math.log(p) / n);
/** Enough decimals to show how close to 100 a percentile is: p96.6, p99.95, p99.995. */function pName(x: number): string { if (x >= 100) return "p100"; const decimals = Math.min(6, Math.max(1, Math.ceil(-Math.log10(100 - x)) + 1)); return `p${x.toFixed(decimals).replace(/(\.\d*?)0+$/, "$1").replace(/\.$/, "")}`;}
/** A computed share: three significant figures in the range that matters, never rounded to 0% or 100%. */function share(f: number): string { const v = f * 100; if (v >= 99.995) return v >= 100 ? "100%" : ">99.99%"; if (v >= 10) return `${v.toFixed(1)}%`; if (v >= 0.01) return `${v.toFixed(2)}%`; return `${v.toPrecision(2)}%`;}
/** A share as the reader typed it: 0.5%, not 0.50%. */const typed = (q: number) => `${Number((q * 100).toPrecision(6))}%`;
/** 1000 as 1,000, without leaning on Intl. */const comma = (n: number) => String(n).replace(/\B(?=(\d{3})+(?!\d))/g, ",");
const callsWord = (n: number) => `${comma(n)} call${n === 1 ? "" : "s"}`;
const capital = (s: string) => s.charAt(0).toUpperCase() + s.slice(1);
const SHARE = /(\d+(?:\.\d+)?|\.\d+)\s*%/g;const PERCENTILE = /\bp(\d+(?:\.\d+)?)\b/gi;/** A count: not part of a word such as s3, and allowed to be written 20x or 20 calls. */const COUNT = /(?<![\w.])\d+(?:\.\d+)?(?=$|[\s,;:×]|x\b|calls?\b)/gi;
/** "0.5%", "0.5" or "p99" as the share of calls that are slow. A bare number is a percentage. */function parseSlow(text: string): number { const t = text.trim(); const pct = /^(\d+(?:\.\d+)?|\.\d+)\s*%?$/.exec(t); if (pct) { const v = Number(pct[1]); if (v > 0 && v < 100) return v / 100; } const pc = /^p(\d+(?:\.\d+)?)$/i.exec(t); if (pc) { const v = Number(pc[1]); if (v > 0 && v < 100) return (100 - v) / 100; } throw new InputError("Write the share of calls that are slow, such as 0.5%, or the percentile at your limit, such as p99.", "slow");}
/** "p99", "P99.9" or "99" as the share of requests that must be fast. */function parseTarget(text: string): Target { const m = /^\s*p?(\d+(?:\.\d+)?)\s*%?\s*$/i.exec(text); const v = m ? Number(m[1]) : Number.NaN; if (!(v > 0 && v < 100)) throw new InputError("Write the percentile you promise for the whole request, such as p99 or p99.9.", "target"); return { p: v / 100, name: `p${v}` };}
/** * Dependencies, one per line or separated by commas: a name, how many calls one request makes to it (1 if left * out), and its share of slow calls, as a percentage or as the percentile at the reader's limit. So `pricing 20 * 0.5%`, `pricing: 20 calls, 0.5%`, `tax 0.2%` and `shards 20 p99` all read. A piece with no share yet, such as * the `pricing: 20 calls` before the comma in the long form, is joined to the next one. */function parseDependencies(text: string): Dependency[] { type Piece = { at: number; text: string }; const hasShare = (s: string) => /(\d+(?:\.\d+)?|\.\d+)\s*%/.test(s) || /\bp\d/i.test(s); const pieces: Piece[] = []; let offset = 0; for (const line of text.split("\n")) { const lineAt = offset; offset += line.length + 1; if (line.trim().startsWith("#")) continue; let pending: Piece | null = null; let at = lineAt; for (const chunk of line.split(/[,;]/)) { const piece: Piece = pending ? { at: pending.at, text: `${pending.text},${chunk}` } : { at, text: chunk }; at += chunk.length + 1; if (piece.text.trim() === "") { pending = null; } else if (hasShare(piece.text)) { pieces.push(piece); pending = null; } else pending = piece; } if (pending) pieces.push(pending); }
const out: Dependency[] = []; for (const piece of pieces) { const lead = piece.text.length - piece.text.trimStart().length; const whole = [piece.at + lead, piece.text.trim().length] as const; const span = (m: RegExpMatchArray) => [piece.at + (m.index ?? 0), m[0].length] as const; const shares = [...piece.text.matchAll(SHARE)]; const percentiles = [...piece.text.matchAll(PERCENTILE)]; const blanked = piece.text.replace(SHARE, (m) => " ".repeat(m.length)).replace(PERCENTILE, (m) => " ".repeat(m.length)); const counts = [...blanked.matchAll(COUNT)]; const name = blanked .replace(COUNT, " ") .replace(/\b(calls?|x)\b|[:×,]/gi, " ") .replace(/\s+/g, " ") .trim() .slice(0, 40) || `dependency ${out.length + 1}`; if (shares.length + percentiles.length !== 1 || counts.length > 1) { throw new InputError( "Write each dependency as a name, its calls per request and its share of slow calls, such as pricing 20 0.5%.", "dependencies", ...whole, ); } const calls = counts.length === 1 ? Number(counts[0]![0]) : 1; if (!Number.isInteger(calls) || calls < 1 || calls > MAX_CALLS) { throw new InputError(`${name}: the calls per request must be a whole number from 1 to 100,000.`, "dependencies", ...span(counts[0]!)); } let q: number; if (shares.length === 1) { q = Number(shares[0]![1]) / 100; if (!(q > 0 && q < 1)) throw new InputError(`${name}: the share of slow calls must be above 0% and below 100%.`, "dependencies", ...span(shares[0]!)); } else { const p = Number(percentiles[0]![1]); if (!(p > 0 && p < 100)) throw new InputError(`${name}: write the percentile at your limit, such as p99.`, "dependencies", ...span(percentiles[0]!)); q = (100 - p) / 100; } out.push({ name, calls, q }); } if (out.length > MAX_LINES) throw new InputError(`List at most ${MAX_LINES} dependencies.`, "dependencies"); if (out.reduce((a, d) => a + d.calls, 0) > MAX_CALLS) throw new InputError("A request can make at most 100,000 calls in all.", "dependencies"); return out;}
/** Calls per request from 1 to well past the reader's own, on a log axis, so the knee is always in view. */function callAxis(calls: number): number[] { const top = Math.max(100, 10 ** Math.ceil(Math.log10(calls * 4))); const xs: number[] = []; for (let decade = 1; decade < top; decade *= 10) for (const m of [1, 2, 5]) if (decade * m <= top) xs.push(decade * m); if (!xs.includes(top)) xs.push(top); if (!xs.includes(calls)) xs.push(calls); return xs.sort((a, b) => a - b);}
const factor = (d: Dependency) => `(1 - ${typed(d.q)})${d.calls === 1 ? "" : `^${d.calls}`}`;
/** The headline number, and the arithmetic that makes it, set against what the target allows. */function headline(hit: number, arithmetic: string, target: Target): Output[] { return [ { kind: "fields", role: "key", fields: [{ label: "Requests that wait for a slow call", value: share(hit) }] }, { kind: "text", role: "formula", mono: true, text: `${arithmetic} · a ${target.name} target allows ${typed(1 - target.p)}` }, ];}
/** The per-call percentile, set against the calls' own when there is one share to compare it with. */function needs(total: number, target: Target, current?: number): string { const need = allowedPerCall(target.p, total); const each = total === 1 ? "the call needs" : current === undefined ? `each of the ${comma(total)} calls needs` : "each call needs"; const head = `For ${target.name} on the request, ${each} ${pName(100 * (1 - need))}.`; if (current === undefined) return head; const at = pName(100 * (1 - current)); const yours = total === 1 ? "Your call" : "Your calls"; return current <= need * (1 + 1e-9) ? `${head} ${yours}, at ${at}, already ${total === 1 ? "meets" : "meet"} it.` : `${head} ${yours} ${total === 1 ? "is" : "are"} at ${at}.`;}
const ASSUMES = { label: "Assumes", mono: false, value: "Calls are slow independently of each other, and the request waits for all of them. Calls that share a host, a network path or a pause are slow together, so measure your own requests and use this as the baseline.",};
function single(d: Dependency, named: boolean, target: Target): Output[] { const hit = slowFrom(d.q, d.calls); const xs = callAxis(d.calls); return [ ...headline(hit, `1 - (1 - ${typed(d.q)})^${d.calls}`, target), { kind: "text", role: "answer", text: needs(d.calls, target, d.q) }, { kind: "series", chart: { xLabel: named ? `Calls per request to ${d.name}` : "Calls per request", yLabel: "Requests with a slow call", yUnit: "%", xScale: "log", x: xs, series: [ { label: `${typed(d.q)} of calls slow`, shape: "line", markers: true, points: xs.map((n) => Number((slowFrom(d.q, n) * 100).toFixed(3))) }, ], annotations: [{ x: d.calls, label: callsWord(d.calls) }], }, }, { kind: "fields", role: "method", fields: [ ASSUMES, { label: "How it is worked out", mono: false, value: "A request is fast only if every call is. With n calls, each slow a share q of the time, 1 - (1 - q)^n of requests are slow. For a share p of requests to be fast, each call must be fast with probability p^(1/n), which is the percentile it needs.", }, ], }, ];}
function several(deps: Dependency[], target: Target): Output[] { const total = deps.reduce((a, d) => a + d.calls, 0); const hit = slowRequests(deps); const shown = deps.length > 3 ? [factor(deps[0]!), factor(deps[1]!), "...", factor(deps.at(-1)!)] : deps.map(factor); // Worst first. The requests a dependency slows on its own and what is left without it give the same order, // since without = 1 - (1 - hit) / (1 - alone). const ranked = deps .map((d) => ({ d, alone: slowFrom(d.q, d.calls), without: slowRequests(deps.filter((x) => x !== d)) })) .sort((x, y) => y.alone - x.alone); const first = ranked[0]!; const its = first.d.calls === 1 ? "its call slows" : `its ${comma(first.d.calls)} calls slow`; const lead = hit > 1 - target.p ? `Fix ${first.d.name} first` : `${capital(first.d.name)} matters most`; const rows = ranked.slice(0, TABLE_ROWS); return [ ...headline(hit, `1 - ${shown.join(" × ")} · ${callsWord(total)} to ${deps.length} dependencies`, target), { kind: "text", role: "answer", text: `${needs(total, target)} ${lead}: ${its} ${share(first.alone)} of requests on ${first.d.calls === 1 ? "its" : "their"} own.`, }, { kind: "table", role: "comparison", caption: `Fix first: slow requests without each one${deps.length > rows.length ? `, top ${rows.length} of ${deps.length}` : ""}`, columns: [ { label: "Dependency", wrap: "none", rowHeader: true }, { label: "Calls", align: "end", mono: true, wrap: "none" }, { label: "Slow calls", align: "end", mono: true, wrap: "none" }, { label: "Without it", align: "end", mono: true, wrap: "none" }, ], rows: rows.map(({ d, without }): Cell[] => [d.name, { text: comma(d.calls), mono: true }, { text: typed(d.q), mono: true }, { text: share(without), mono: true }]), }, { kind: "fields", role: "method", fields: [ ASSUMES, { label: "How it is worked out", mono: false, value: "A request is fast only if every call is, so multiply each dependency's chance of being fast: 1 - (1 - q1)^n1 × (1 - q2)^n2 × ... of requests are slow. Without it means that dependency is never slow. The per-call percentile holds every call to the same share, p^(1/n) for n calls in all.", }, ], }, ];}
export default { run({ calls, slow, target, dependencies }: Input) { try { const t = parseTarget(String(target ?? "")); const deps = parseDependencies(String(dependencies ?? "")); if (deps.length > 1) return { kind: "group", parts: several(deps, t) }; if (deps.length === 1) return { kind: "group", parts: single(deps[0]!, true, t) }; if (!(Number.isInteger(calls) && calls >= 1 && calls <= MAX_CALLS)) { throw new InputError("The calls per request must be a whole number from 1 to 100,000.", "calls"); } return { kind: "group", parts: single({ name: "", calls, q: parseSlow(String(slow ?? "")) }, false, t) }; } catch (error) { if (error instanceof InputError) { return { kind: "error", message: error.message, input: error.input, ...(error.at !== undefined ? { at: error.at } : {}), ...(error.len !== undefined ? { len: error.len } : {}), }; } throw error; } },} satisfies Tool<Input>;
Toolbench is a small framework for interactive tools in web pages. A tool is a pure function and a JSON manifest, and the runtime builds the form, runs the function and draws the answer. What it is, how it fits together, and the choices behind it, shown with tools that run live on mainLog.
The internals of toolbench, the framework behind mainLog's tools: what the runner guards against, why a worker exists only to be terminated, how a graph is laid out and routed the same in every browser, how known answers and size budgets keep tools honest, and why every migration is the identity function.
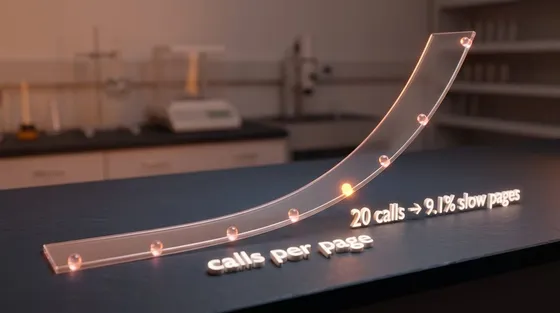
A checkout page hangs while the dashboard says 23 ms. The mean, a percentile and a share under a threshold each answer a different question, only two of them add up across hosts, and an averaged p99 can be wrong by a factor of three in either direction.
Habits most codebases rely on without ever stating them.
Toolbench is a small framework for interactive tools in web pages. A tool is a pure function and a JSON manifest, and the runtime builds the form, runs the function and draws the answer. What it is, how it fits together, and the choices behind it, shown with tools that run live on mainLog.
The internals of toolbench, the framework behind mainLog's tools: what the runner guards against, why a worker exists only to be terminated, how a graph is laid out and routed the same in every browser, how known answers and size budgets keep tools honest, and why every migration is the identity function.
A checkout page hangs while the dashboard says 23 ms. The mean, a percentile and a share under a threshold each answer a different question, only two of them add up across hosts, and an averaged p99 can be wrong by a factor of three in either direction.

