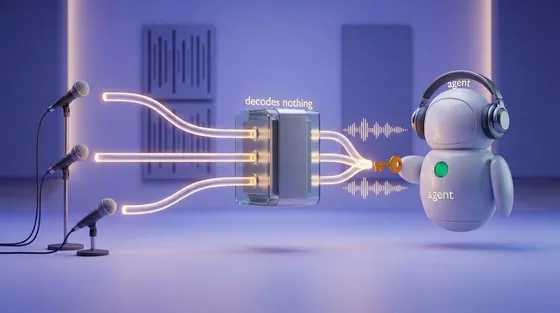
SFU, MCU, and the participant that has to decode
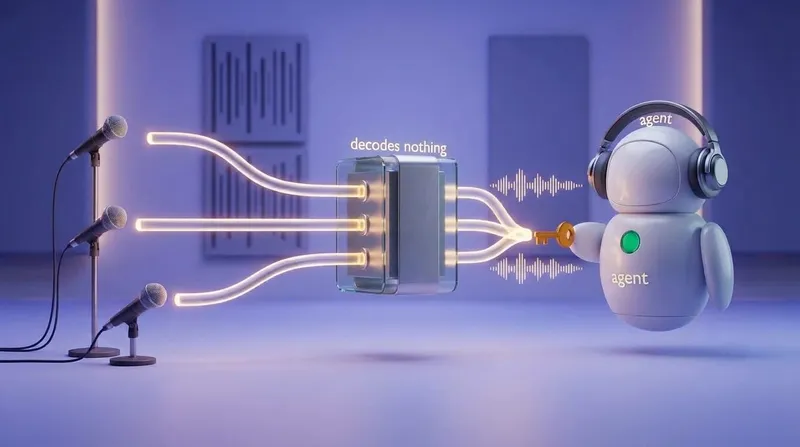
Put an AI agent in a group call and two questions decide the design: does the model hear each person, or one blend, and who has to hold the keys? Both come down to where the agent's audio gets decoded.
ai-agentswebrtcarchitecture